Supabase
 ChatGPT
 Claude
 Gemini
For the last few years every AI model has done roughly the same job. You type something in, it thinks for a bit, and it writes something back. Faster models, cheaper models, models that can see images, but always the same shape. Then in mid September a small San Francisco company called TypeSafe AI released a model called Jev that refuses to write anything at all.
The claims flying around (200 times faster, 400 times cheaper, "cannot hallucinate") set off our anti-hype alarm, so we read what TypeSafe actually says, what independent testers found, and what people have built with it. This deep dive covers what Jev is, where it is genuinely useful for the kind of things you build, and where the hype runs ahead of reality.
A small demo from a builder called Rock shows the idea well. He fed a simulated car's surroundings to Jev ten times a second and had it choose between braking, accelerating, slowing down and changing lanes, with obstacles, pedestrians and red lights thrown in.
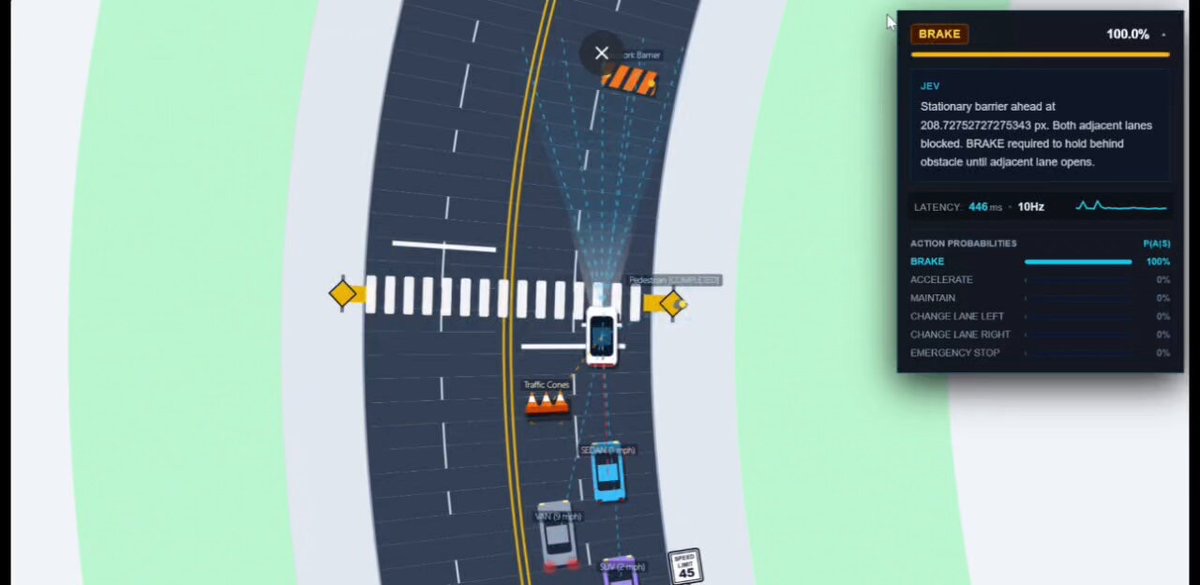
Jev picking "brake" with a barrier ahead, from Rock's video on X.
01 / 06
What Jev actually does
Jev borrows an idea from the psychologist Daniel Kahneman, who split human thinking into two modes. System One is the fast, automatic kind. You glance at an email and know it's spam. System Two is the slow, deliberate kind, like working out 17 times 24 or writing a tricky reply.
ChatGPT, Claude and Gemini are System Two machines. Even for a yes or no question, they write their way to the answer one word at a time. TypeSafe calls Jev a System One model. It only answers questions where you've already written down the possible answers.
You give it two things. First, some raw material, which TypeSafe calls the state. That might be an email, a form submission, or the text of a web page. Second, a set of questions with fixed answers. Which team should handle this, billing, technical or account. How severe is it from one to five. Is the customer asking for a refund.
Jev sends back a probability for every option, rather than a sentence. In TypeSafe's own example, a support ticket comes back as 91% technical, 8% billing, 1% account, and 97% likely to be asking for a refund. Think of it less like a chatbot and more like a very well read sorting hat. It never explains itself, it just points.
02 / 06
Why it's so fast and so cheap
Because Jev never generates text, it skips the slow part of what normal models do. TypeSafe quotes 70 to 500 milliseconds per answer, and independent testers have measured a typical call at somewhere between a tenth and a quarter of a second. A chatbot answering the same question usually takes a few seconds.
The pricing is what made people sit up. Jev charges $0.042 per million input tokens, and output is free. A token is roughly three quarters of a word, so classifying a typical support email costs about two thousandths of a cent. The big models from OpenAI, Anthropic and Google charge somewhere between $1 and $10 or more per million tokens, and charge again for what they write back.
The name is a nod to William Stanley Jevons, a Victorian economist who noticed that more efficient steam engines led to Britain burning more coal, not less. The bet is that when a decision costs almost nothing, you'll make millions more of them.
03 / 06
Real-world examples
The demos from the four weeks since launch give a good feel for where this fits.
- Sorting 1,700 emails for 18 cents. Ryan Vogel demonstrated this on Greg Isenberg's podcast, pushing an inbox export through Jev and tagging each message by department, priority and reply urgency, at about 200 milliseconds a message.
- A faster browser agent. The browser-use team wired Jev in to pick which element to click next. Their agent found Zürich to London flights on Google Flights in 7.1 seconds, down from a median of 9.5 without it, using about 100 browser calls instead of over 1,000. It searched rather than booked, and they call it a demo, not a benchmark.
- Decluttering web pages. Unclutter, an open source extension by the developer Kitze, asks Jev to sort every element on a page into keep, ad, promotion, newsletter box, social widget or cookie banner, then hides anything it's at least 90% sure about.
- An AI slop detector. On madewithjev.com, an independent showcase site, Jon Kraayenbrink built a tool that scores web copy on 34 tells of AI writing. It rates anthropic.com at 26% and stripe.com at 27%, both "mostly human".
- Playing Doom. TypeSafe's founder had Jev make ten moves a second from a text description of the game, for about $7 an hour. He also admitted a non-AI bot would play better.
04 / 06
How you'd actually use it
Jev is an API, so anything that can make a web request can use it. You send the text or record you want judged plus your questions in plain English, and it sends back the probabilities. It slots into Make, n8n, Bubble or a Zapier webhook step, or into whatever Claude Code or Codex is building for you, and TypeSafe publishes a skill for Claude Code and Codex so your coding agent can wire it up for you.
If you'd rather stay out of code, there is a native Zapier app called TypeSafe Jev with one action, Ask Questions, which returns the answers with their probabilities and lets you set a minimum confidence. TypeSafe's own sign-ups were paused in late September, so Vercel's AI Gateway and OpenRouter are the way in for now.
The confidence number is the useful part. TypeSafe trained Jev with a method they call Reinforcement Learning for Calibrated Decisions, and the aim is that its probabilities mean what they say. Across a batch of decisions it marked 80% likely, roughly 80% should turn out right. Normal chatbots are famously overconfident, because they were trained to sound convincing.
Calibrated probabilities let you build sensible rules. Above 90%, let the automation act. Between 10% and 90%, send it to a human or to a slower, smarter model. Below 10%, bin it. Jev becomes a cheap bouncer at the front door, and your expensive model only sees the hard cases.
05 / 06
The reality check
The claim that Jev cannot hallucinate is only partially true.
TypeSafe guarantees that the answer will always be one of your options. A chatbot asked for a category sometimes returns a paragraph, or invents a fourth category, and that breaks whatever you built downstream. Jev can't do that. But it can still pick the wrong option with a straight face, and TypeSafe's founder has said as much.
How often it's wrong depends on the task. On TypeSafe's own tests Jev scores a little below Claude Opus 5 and GPT-6 on accuracy. An independent evaluation by Vals.ai found it matched the big models at checking factual claims, then came last of twelve models on a slice of legal questions. Another tester needed five carefully split questions before it beat a cheaper chatbot at spotting phishing. Jev is only as good as the question you ask it, and some questions are too hard to answer on reflex.
It also has hard limits that no clever prompting gets round.
- It cannot write anything, so no drafting replies, summaries or code.
- It cannot reason step by step, count things or do maths.
- It has no memory between calls. Every request is a fresh snapshot, which is why it struggles at Doom. It sees the frame in front of it with no idea what it did a second ago.
- Input is capped at around 32,000 tokens, roughly 25,000 words, and text only.
- The architecture and training method are unpublished, so the calibration claims rest on trust plus independent tests.
Two misuses are already doing the rounds. Using Jev to judge whether code or long reasoning is correct, and using it to compress chat histories for agents. Both are System Two jobs. Judging a reasoning trace means following it, and summarising a conversation means writing.
06 / 06
What this means for you
A useful rule of thumb is to ask whether a sharp human could make the decision in under ten seconds without thinking hard. Spam or not spam, which inbox, how urgent, which category, does this lead have a budget. Those are Jev jobs. Anything that needs writing, explaining or working through is a job for a normal model.
The interesting builds combine the two. Jev sits at the front sorting and scoring everything for pennies, and the slow model only gets the small share that genuinely needs thought. If you run a form, an inbox or any automation that currently sends everything to ChatGPT, that is the pattern to try.
Start small. One question, a confidence threshold, and route anything uncertain to yourself for a week, whether that lives in a Zap or in a few lines your coding agent writes. You'll find out quickly whether your question is a reflex question or a thinking one.
Written by
Kieran Ball
Co-founder, Create With
Written by
James Devonport
Co-founder, Create With
The Create With Briefing
Get the next edition first.
Real-life use cases, the tool changes that matter, and the best events near you. Free, every Tuesday, to 8,600+ readers.